Google Cloud has opened a preview of PostgreSQL for agents in AlloyDB, a new architecture that gives AI agents read-only access to fresh production data through isolated database instances. Those instances start in seconds, share the underlying storage used by the operational database and scale back to zero when the work ends.
The design targets a problem that ordinary chatbot demos rarely expose: an agent may turn one user request into many schema checks, retries, joins and vector searches. Point enough agents at a primary database or a conventional read replica and their unpredictable bursts can compete with customer-facing workloads. AlloyDB’s answer is to separate the agents’ query compute from the primary, standby and existing read-replica instances while keeping the data up to date.
The preview is technically significant, but it is not a blanket permission to connect autonomous software to sensitive records. Isolation can protect production performance. Teams still have to control which rows and columns an agent can see, how much it can retrieve, where results travel and which write operations are allowed elsewhere in the workflow.
How AlloyDB isolates agent queries
Traditional PostgreSQL deployments often absorb additional reads with replicas. That model works when traffic is reasonably predictable, but agent loops can be unusually spiky: a planner may inspect a schema, generate SQL, test it, revise the query and fan work out to other agents before returning one answer.
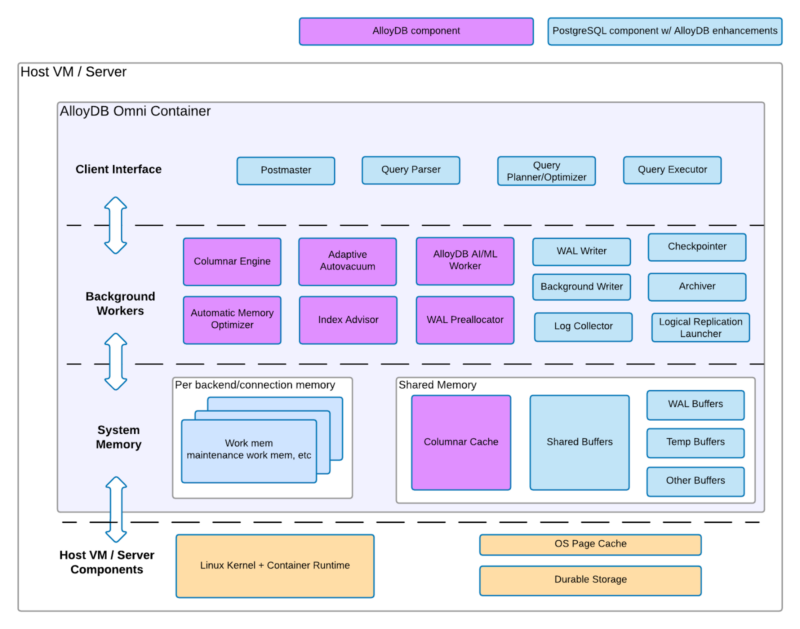
Google’s architecture provisions sandboxed PostgreSQL instances against a shared storage layer built on Colossus. The agent instances receive up-to-the-second, read-only access to production data, but their CPU and memory load remains separate from the instances handling transactions and normal replicas. Each sandbox runs the full AlloyDB PostgreSQL engine, so it can use ordinary SQL and existing indexes as well as vector, full-text and spatial search.
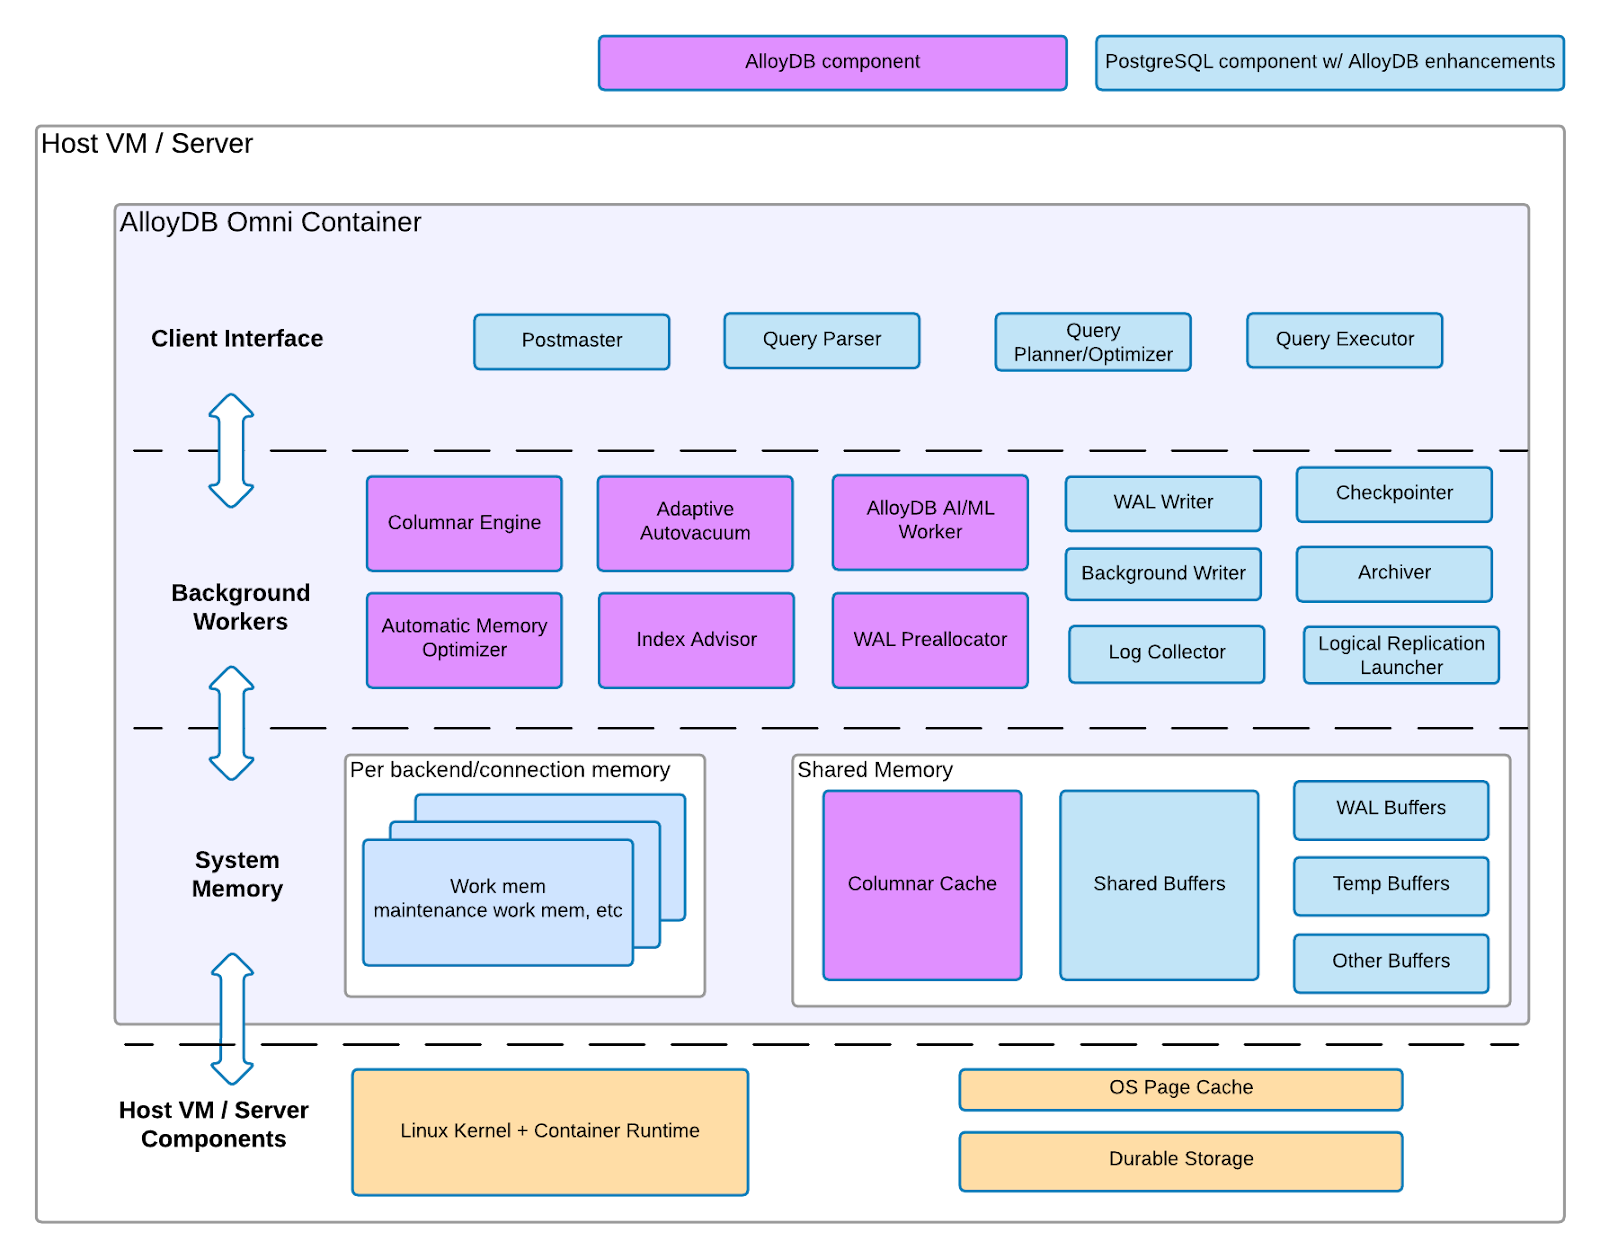
That separation is the central feature, not the “agentic database” label. A poorly generated query can still be expensive, but the expense is intended to land on disposable agent compute rather than slow the checkout, inventory or account system using the primary database.
Google claims sub-millisecond storage I/O, more than one terabit per second of aggregate scan bandwidth and support for more than 3 million queries per second. Those are vendor figures for the architecture, not a published independent benchmark of a reader’s schema, query mix or region. The feature is also covered by Google’s pre-GA terms, is available as-is with potentially limited support and requires an access request.
Why read-only access can still hurt production
Read-only is often treated as a safety boundary because it prevents an agent from deleting or changing records. It does not make the workload harmless. Large joins, repeated scans, missing filters and retry storms can exhaust CPU, memory, I/O or connection pools. Even a correct query can become disruptive when hundreds of agents issue it at once.
OpenAI described a similar failure pattern in a January engineering account of the PostgreSQL systems behind ChatGPT. Cache failures, expensive multi-way joins and traffic spikes could raise latency, cause timeouts and trigger retries that amplified the original load. OpenAI ultimately used extensive application controls and nearly 50 read replicas to sustain millions of read-heavy queries per second. The example was not about AlloyDB, but it illustrates why simply adding agent traffic to an existing replica tier is an operational gamble.
Google is effectively offering transient read compute as a buffer between agent behavior and the transactional cluster. Because instances scale down when idle, customers do not have to keep enough conventional replica capacity running around the clock for the largest possible burst. Google has not publicly listed preview pricing on the product page, however, so teams cannot yet compare that promise with a provisioned replica or a warehouse using complete cost figures.
Fresh data without an ETL copy
Many companies protect operational databases by copying records into a warehouse or search system before an AI application can use them. That reduces pressure on production but introduces another pipeline, another security surface and some amount of delay. For inventory, fraud, logistics or customer-support agents, yesterday’s copy may be useless.
The AlloyDB preview keeps transactional records in shared storage and gives the isolated instances a current read view. Agents can mix B-tree lookups with vector, keyword and spatial queries, and Google says they can federate work across BigQuery and Spark without a separate batch ETL pipeline. A supply-chain agent, for example, could compare a live order with historical demand data without running its analytical scan on the primary database.
The surrounding AlloyDB AI stack already includes a managed Model Context Protocol server with IAM authentication, integrations for LangChain and LlamaIndex, hybrid search, database-side embedding functions and the QueryData natural-language interface. The new instances address compute isolation; those other components determine how an agent connects, converts requests to queries and returns results.
Performance isolation is not data governance
An isolated instance can prevent one class of outage while leaving the harder disclosure questions intact. If an agent’s database role can read every customer row, isolation does not stop it from retrieving too much information. If a prompt-injection attack changes the question, the database still needs enforceable limits that do not depend on the model following instructions.
Production designs should keep authorization below the prompt layer. That normally means a distinct agent identity, least-privilege grants, row-level security or restricted views, column masking for sensitive fields and short-lived credentials. Query timeouts, concurrency caps, row limits and cost budgets should be enforced at the connection or database layer. Logs need to connect the original user, agent run, generated SQL and returned data so an investigation can reconstruct what happened.
Teams should also decide what happens after the query. A safe read can become a data leak if its result is pasted into an external model context, stored in long-lived agent memory or posted to a broadly shared channel. Retention, model-provider settings and outbound tool permissions belong in the same review as database access.
Writes require a separate path. The preview instances are read-only, so an agent that wants to adjust an order or approve a refund must call another service or database endpoint. That boundary is useful when it forces validation and human approval, but it only works if the write service independently checks identity, scope, business rules and idempotency.
What teams should test in the preview
A useful proof of concept should begin with one bounded, read-heavy workflow rather than an open-ended agent. Give it a representative schema and realistic data volume, then measure the number of SQL attempts per request, instance start time, data freshness, latency at burst concurrency and the cost of idle-to-active cycles.
- Failure containment: Run deliberately expensive and malformed queries and confirm that primary and replica latency remain unchanged.
- Access enforcement: Try cross-tenant requests, restricted columns and prompt-injected instructions to verify that database policy, not the model, blocks them.
- Result accuracy: Compare generated answers with known SQL. A September text-to-SQL preprint using 100 questions against the Chicago crime database reported 93% valid SQL but only 60% execution accuracy under its more permissive metric, a reminder that runnable queries can still return the wrong answer.
- Cost controls: Test retry loops and concurrent fan-out, then determine which query, row and time budgets stop one task from multiplying its bill.
- Audit quality: Confirm that security and data teams can trace every statement and result to a human request, agent identity and downstream action.
PostgreSQL for agents in AlloyDB does not solve agent reliability, authorization or data-loss prevention. It does give database teams a clearer architectural option for the performance problem: let agents explore current operational data on ephemeral, isolated compute while the systems serving customers remain separate. Whether that is cheaper and easier than replicas, warehouses or purpose-built APIs will depend on pricing, regional availability and production evidence that Google has not yet published.
Sources: Google Cloud announcement, Google Cloud preview documentation, AlloyDB AI documentation, OpenAI PostgreSQL engineering report and text-to-SQL engineering preprint.