


Browsing Tag
vLLM
2 posts
vLLM inference engine, model serving, performance, deployment, and ecosystem coverage.
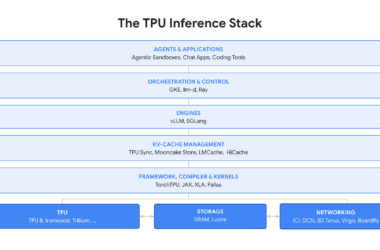
Meta Runs Google TPUs in Production as TorchTPU Opens the Stack
Meta is serving production AI workloads on Google TPUs through TorchTPU. Here is what the PyTorch-native stack supports, where it remains uneven, and what teams should test.

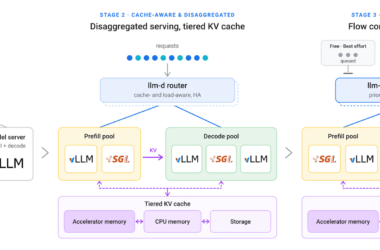
llm-d 1.0 Brings Agent-Aware Routing to Kubernetes AI Inference
llm-d 1.0 stabilizes APIs, adds agent-aware routing and coordinates zero-downtime inference upgrades. Here is what platform teams should test before migrating.